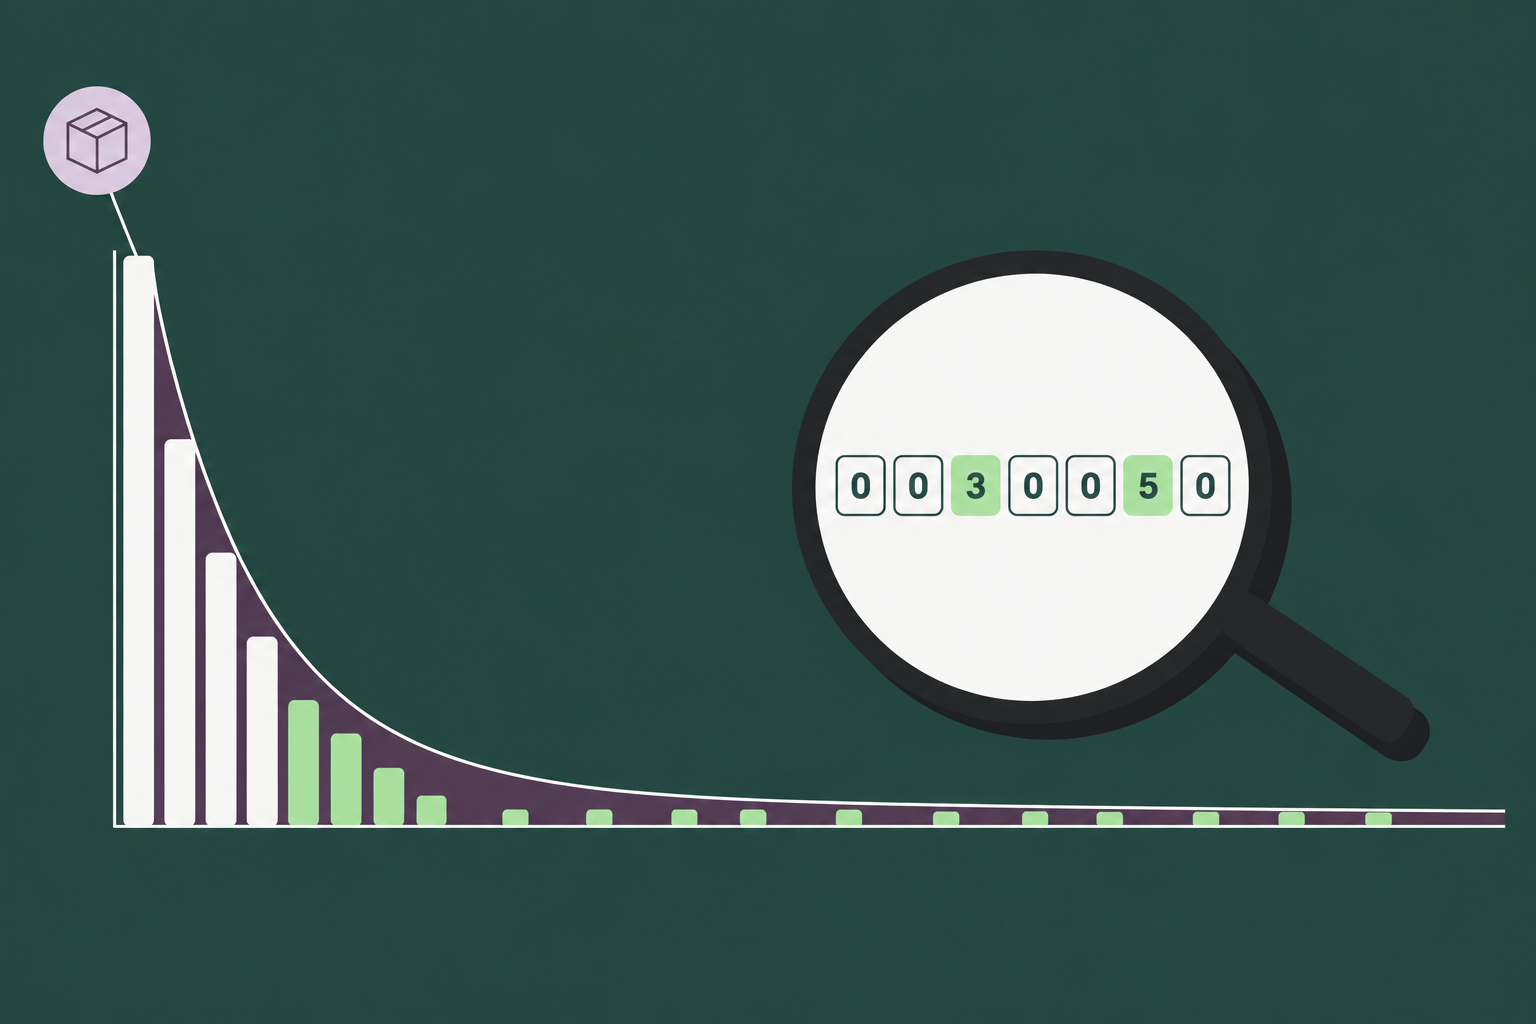
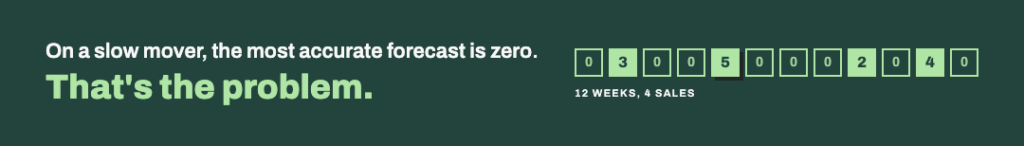
Here’s an awkward fact about slow movers. For a SKU that sells one week in three, the forecast with the lowest MAE and WMAPE is zero, every week. It’s also the one forecast guaranteed to stock you out.
That’s the trouble with intermittent demand forecasting. Standard models treat the zeros as noise and get the timing wrong in a predictable direction, and standard metrics reward the wrong answer. In a long tail catalog, that covers most of the SKU list. Kostas Nikolopoulos titled a paper in the European Journal of Operational Research “We need to talk about intermittent demand forecasting”, and the title is fair.
Our view: on a sparse SKU, the forecast is a rate that feeds a stocking decision, and it should be judged by that decision. Which method you run matters less than classifying the SKU correctly, measuring it in a way that zeros can’t game, and knowing when to stop forecasting it.
This guide covers the ADI/CV² matrix for classifying demand, Croston’s method and its two fixes, and one 12-week SKU run through four methods side by side.
What is intermittent demand?
Intermittent demand is demand that occurs sporadically, with many periods of zero sales between periods with sales. The timing of the next sale is uncertain, and often its size is too. It’s typical of spare parts, long tail products and other slow moving inventory.
You’ll find it in a few familiar places:
- Spare parts and MRO: a part is needed when something breaks
- Long tail e-commerce: thousands of listings that each sell a handful of units a year
- B2B industrial products: items ordered by a few customers at irregular intervals
- Pharma SKUs at store level: steady nationally, sporadic at any one location
The pharma case shows that intermittency depends on where you measure. The same SKU can be smooth at national-month level and sparse at store-day level, so some intermittent demand is a choice of granularity.
Intermittent vs. lumpy vs. smooth demand: the ADI/CV² matrix
Before you pick a method, classify the SKU. Two numbers do it.
- ADI (average demand interval) = total number of periods ÷ number of periods with demand. It measures how often the item sells.
- CV² (squared coefficient of variation) = (standard deviation of the non-zero demand sizes ÷ their mean)². It measures how much the size of a sale varies. Zero periods are left out.
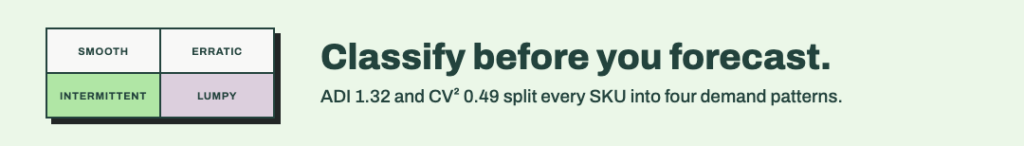
The standard cut-offs are an ADI of 1.32 and a CV² of 0.49. They come from Syntetos, Boylan and Croston (2005), who validated them on 3,000 real demand series from the automotive industry. Together they split every SKU into one of four patterns:
| CV² below 0.49 (sale sizes are steady) | CV² of 0.49 or more (sale sizes vary) | |
| ADI below 1.32 (sells in most periods) | Smooth. Exponential smoothing or ETS. | Erratic. Driver-based or ML models. |
| ADI of 1.32 or more (many zero periods) | Intermittent. Croston or SBA. | Lumpy. SBA or TSB, or aggregate up (weekly to monthly, SKU to family). |
In the original paper the cut-offs mark where SBA’s expected error beats Croston’s, so SBA is the safer default anywhere outside the smooth quadrant. Erratic items are a different case. They sell often enough that the swings in size usually have a cause, which is why models built on demand drivers suit them better than anything in the Croston family.
Why standard forecasting methods fail on sparse SKUs
Simple exponential smoothing and moving averages are the default demand forecasting methods in most planning systems, and both assume demand shows up every period. Feed them a sparse series and they produce a sawtooth. The forecast drops after every zero and jumps after every sale.
The pattern has an unfortunate shape. The forecast is at its highest right after a sale and at its lowest just before the next one. Croston noticed in 1972 that this is the wrong way round for inventory, because replenishment usually gets triggered by a sale. You reorder at the moment the forecast is most inflated.
In the worked example below, the exponential smoothing forecast swings between 1.13 and 1.60 units a week over 12 weeks, on a SKU whose underlying rate never changed.
Croston’s method: how it works, with a worked example
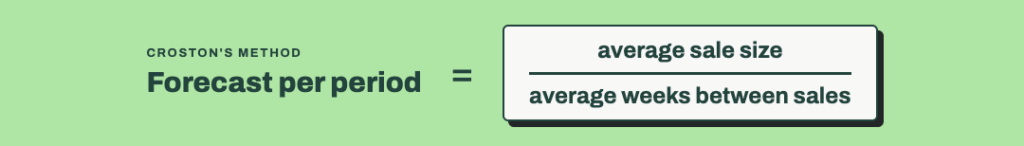
Croston’s method forecasts intermittent demand by smoothing two things separately: the size of each non-zero demand, and the number of periods between demands. Both are updated only in periods when demand occurs. The forecast of demand per period is the smoothed size divided by the smoothed interval.
In plain terms, with a smoothing constant alpha:
- New size estimate = old size estimate + alpha × (latest sale size − old size estimate)
- New interval estimate = old interval estimate + alpha × (latest interval − old interval estimate)
- Forecast per period = size estimate ÷ interval estimate
Alpha is usually set low. Hyndman and Athanasopoulos note that R’s croston() function uses 0.1 by default, and we use the same here.
The example. Take one SKU with 12 weeks of demand: 0, 3, 0, 0, 5, 0, 0, 0, 2, 0, 4, 0. That’s 14 units, or 1.17 a week. It sold in 4 of 12 weeks, so ADI = 12 ÷ 4 = 3.0. The four sale sizes average 3.5 with a CV² of 0.10. High ADI, low CV²: the intermittent quadrant.
The first sale sets the starting values: a size of 3 and an interval of 2 weeks. After that, Croston updates only when a sale lands.
| Week | Sale | Weeks since last sale | Size estimate | Interval estimate | Forecast (units/week) |
| 2 | 3 | 2 | 3.00 | 2.00 | 1.50 |
| 5 | 5 | 3 | 3.20 | 2.10 | 1.52 |
| 9 | 2 | 4 | 3.08 | 2.29 | 1.34 |
| 11 | 4 | 2 | 3.17 | 2.26 | 1.40 |
Week 5 shows the arithmetic. Size: 3 + 0.1 × (5 − 3) = 3.2. Interval: 2 + 0.1 × (3 − 2) = 2.1. Forecast: 3.2 ÷ 2.1 = 1.52.
Read the result as a rate. A forecast of 1.40 means about 1.4 units a week on average, or five to six over a four-week lead time. Nobody expects 1.4 units to sell next week. In the zero weeks nothing moves: through weeks 6, 7 and 8 the forecast sat at 1.52. That stability is what Croston is for, and it’s also the weakness. If this item stopped selling tomorrow, the forecast would stay at 1.40 indefinitely.
SBA and TSB: fixing Croston’s bias
Croston’s method runs high. It divides an average size by an average interval, and dividing by an average isn’t the same as averaging the divisions. Syntetos and Boylan identified the upward bias in 2001 and later proposed the fix that carries their names. Their book, Intermittent Demand Forecasting, covers all of this in depth.
SBA (the Syntetos-Boylan Approximation) multiplies Croston’s forecast by (1 − alpha ÷ 2). At an alpha of 0.1 that’s a 5% reduction, so our 1.40 becomes 1.33. It’s the usual default for intermittent and lumpy items. Teunter and Sani add a caution: the correction can overshoot and leave a negative bias on items that sell in most periods, so keep SBA for SKUs that are sparse to begin with.
TSB (the Teunter-Syntetos-Babai method) changes what gets smoothed. It drops the interval and tracks the probability of a sale, updating it in every period: down a little after each zero week, up after each sale. The size estimate still updates only on a sale. Forecast = size estimate × probability of a sale.
Because TSB keeps learning through the zero weeks, its forecast decays when an item stops selling. That makes it the right choice for SKUs with obsolescence risk, such as end-of-life parts and launches that never took off. The price is that some of the sawtooth comes back.
One SKU, four methods: a side-by-side comparison
We ran the same 12 weeks through all four methods with alpha at 0.1. Each method starts from the same belief, 1.5 units a week, which is what the first sale implies (3 units after 2 weeks).
| Method | Forecast after week 12 (units/week) | Against the actual average of 1.17 | Lowest and highest forecast along the way |
| Simple exponential smoothing | 1.27 | +9% | 1.13 to 1.60 |
| Croston | 1.40 | +20% | 1.34 to 1.52 |
| SBA | 1.33 | +14% | 1.28 to 1.45 |
| TSB | 1.23 | +5% | 1.09 to 1.52 |
Croston finishes highest. A little of that is its bias, which SBA trims. Most of it is that Croston only learns when a sale lands, so it had three chances in 12 weeks to move off its starting point. TSB and exponential smoothing update every week and end closer to the true rate, but their ranges swing by about 40%, and a reorder placed right after a sale would have used the top of that range.
The four also finish close together, between 1.23 and 1.40 units a week. Over a four-week lead time that’s a difference of less than one unit. The service level you choose and the way you measure will move your inventory more than the choice between these methods.
Twelve weeks is a short history, and with this little data the starting values matter. You can change them, along with the demand series and alpha, in our intermittent demand calculator and every number in this table recalculates.
How to measure accuracy when demand is mostly zeros
MAPE fails first. It divides the error by actual demand, and in 8 of our 12 weeks actual demand is zero. Our guide on how to measure forecast accuracy covers the general case.
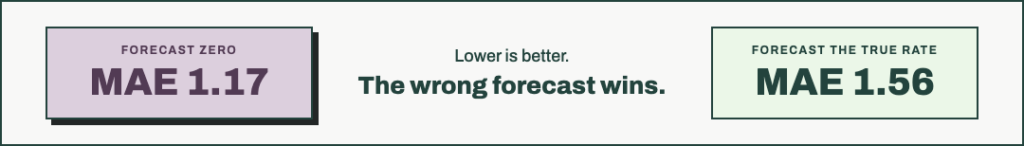
The less obvious trap is that the metrics you can still calculate reward the wrong forecast. Below are two flat forecasts for our SKU, scored week by week:
| Metric | Always forecast zero | Forecast the true average (1.17) |
| MAPE | Undefined in 8 of 12 weeks | Undefined in 8 of 12 weeks |
| MAE | 1.17 | 1.56 |
| WMAPE | 100% | 133% |
| RMSE | 2.12 | 1.77 |
| Bias | −100% | 0% |
| Error on the 12-week total | 100% | 0% |
On MAE and WMAPE, the zero forecast wins. Absolute-error metrics are minimized by the median, and the median week of a slow mover is zero. MASE is a scaled MAE, so it has the same flaw. Stephan Kolassa’s work on evaluating count data forecasts in retail makes the same case against MAD, MASE and wMAPE for this kind of series.
Four things work better:
- Bias, next to every accuracy number. A forecast of zero has a bias of −100%. Don’t sign off a slow-mover forecast on an error metric alone.
- Aggregate before you score. Measure the forecast over the lead time or the quarter, where demand isn’t mostly zeros. WMAPE works at family or monthly level.
- Squared-error metrics, if you have to score at SKU-week level. RMSE and its scaled versions reward the right average.
- Service outcomes. Fill rate achieved against inventory held is what you’re paying for.
There’s research behind the fourth. Nikolaos Kourentzes found that neural network forecasts with “poor forecasting accuracy and bias” still achieved higher service levels than the best Croston variant, without a matching increase in stock. Accuracy metrics and inventory results can point in opposite directions.
Don’t panic at big numbers, either. Our 2026 forecast accuracy report includes a portfolio whose incumbent forecast started at a weighted MAPE of 146%. Errors above 100% are what low-volume, intermittent demand does to a forecast.
Safety stock needs the same care. The textbook safety stock formula assumes demand is roughly normal, and lead-time demand for a sparse item isn’t. Fit a count distribution such as Poisson or negative binomial to the forecast rate, or resample from the SKU’s own history, and set the reorder point from that.
Managing the long tail: slow moving inventory and when to stop forecasting
Long tail products are the many SKUs that each sell rarely. Individually they’re small. Together, long tail inventory ties up a large share of stock and planner time, and all that slow moving inventory drags down your inventory turnover ratio.
Tuning alpha won’t fix that. Three other moves will do more.
Aggregate, then allocate. Forecast at a level where demand is smooth, such as the product family or the month, then split it down by each SKU’s share. This is the practical answer for the lumpy quadrant. The ADIDA study tested aggregation over time on 5,000 SKUs from the Royal Air Force and reported benefits for intermittent items.
Segment before you optimize. An ABC-XYZ grid, which crosses value with variability, shows where precision pays. It’s one of the levers in our guide to inventory optimization. Low-value sparse items should run on rules and stay off the planner’s screen.
Stop forecasting some of them. If a SKU sells twice a year, no method will tell you when. Give it a policy instead:
- Min/max: hold one or two units, reorder when stock hits the minimum, and review the levels twice a year
- Make to order or order on demand: hold nothing and quote a lead time
- Delist: if it hasn’t sold in a year and nothing depends on it
The choice comes down to two costs. If holding a unit is cheap and a stockout is expensive, as with a critical spare part, hold a small fixed quantity. If holding is expensive and the customer will wait, make to order.
Where intermittent demand comes from: new products and end-of-life SKUs
Some intermittent demand is structural: a spare part for a ten-year-old machine will always be sparse. Some of it is a phase.
New products often look intermittent in their first weeks, when distribution is still thin and repeat purchase hasn’t started. Fitting Croston to four weeks of data won’t help. You’ll get a better answer if you forecast demand for a new product from analogs and early signals. At the other end of the life cycle, items fading out turn sparse on their way to zero, which is the case TSB was designed for.
How AI forecasts intermittent demand
A single sparse series gives a model almost nothing to learn from. Our example SKU produced four sales in 12 weeks. Croston-type methods accept that limit and smooth what little is there.
Machine learning takes a different route. A global model trained across thousands of series at once can borrow signal from similar SKUs in the same category, price band, customer base or season. It can also use drivers that a single series can’t reveal, like promotions, price changes, or the installed base behind a spare part. Kourentzes describes the result as “dynamic demand rate forecasts, which do not assume constant demand rate in the future.”
It comes with conditions. A model trained to minimize absolute error will learn to forecast zero, for the reason shown in the metrics table, so the loss function and the evaluation both have to be set up for sparse data. Cross-learning also needs breadth. A few hundred series won’t give it much to borrow from.
This is how we handle the long tail at DemandForecast.ai. One model learns across the portfolio, each SKU is classified by demand pattern, and planners see the exceptions that need a decision. The usual objection to AI forecasting is that it works on tidy, high-volume portfolios and falls over on the long tail. Our accuracy report takes that objection on directly.
FAQ
What is Croston's method for forecasting intermittent demand?
What is the difference between intermittent and lumpy demand?
Why does MAPE not work for intermittent demand?
What is the TSB method?
How do you manage slow moving inventory?
Put the long tail on rules, and your planners on the exceptions
DemandForecast.ai forecasts whole portfolios, slow movers included, and flags the SKUs that need a planner’s decision this week. If your long tail is eating planner hours and working capital, book a demo and bring your own data. We’ll show you what it looks like once every SKU is classified and forecast by pattern.