Forecast bias is the tendency of a forecast to miss in the same direction over time, consistently above actual demand or consistently below it. It is measured as the signed difference between total forecast and total actual over a period, which separates a persistent lean from the random scatter that accuracy metrics such as MAPE and WMAPE describe.
Most guidance treats bias as a single number for the whole forecast, something to shave off with a global adjustment. We would argue bias has an address. In the 12-week dataset below, which is the same dataset our guide to forecast accuracy metrics runs through MAPE, WMAPE and FVA, the forecast carries a +3.8% bias. Remove the two post-promotion weeks and the bias on the other ten is +0.5%. The lean lives in one demand state, and a global trim would have pushed the ten good weeks under while barely touching the two that caused the problem. Finding where bias comes from matters more than measuring how much there is, and the tracking signal, which we add here, is the alarm that tells you when a lean has stopped being luck.
What is forecast bias?
A forecast with 6% error that misses high one week and low the next is noisy. Inventory buffers absorb noise, because the misses cancel. A forecast with 4% error that misses high every week is biased, and nothing absorbs it: every week adds stock the business did not need, or every week leaves demand unserved. Bias is the more expensive kind of error because it compounds, and it is the kind accuracy metrics hide, since MAPE and WMAPE take absolute values and throw the sign away.
It also tends to be structural rather than statistical. Sales teams protect targets, finance anchors to budget, promotion uplifts get applied twice. None of those is a random process, which is why the direction of the error says so much about the planning process that produced it.
The forecast bias formula
Bias % = (sum of forecasts − sum of actuals) ÷ sum of actuals
Positive means the forecast ran high (over-forecasting). Negative means it ran low (under-forecasting). Some teams flip the subtraction so that a positive bias means under-forecasting. Both conventions are in use, so pick one, write it on the dashboard, and never change it. We use forecast minus actual throughout.
In units rather than percent, the same calculation is mean error: the average signed error per period. Percent is easier to compare across SKUs, and units are easier to turn into pallets.
Worked example: 12 weeks of one SKU
Weeks 6 and 10 are post-promotion troughs, the kind of irregular demand that separates a biased forecast from a noisy one.
| Week | Actual | Forecast | Error (forecast − actual) |
| 1 | 950 | 1,000 | +50 |
| 2 | 1,010 | 1,000 | −10 |
| 3 | 980 | 1,000 | +20 |
| 4 | 1,040 | 1,000 | −40 |
| 5 | 990 | 1,000 | +10 |
| 6 | 210 | 400 | +190 |
| 7 | 1,020 | 1,000 | −20 |
| 8 | 970 | 1,000 | +30 |
| 9 | 1,000 | 1,000 | 0 |
| 10 | 240 | 400 | +160 |
| 11 | 1,030 | 1,000 | −30 |
| 12 | 960 | 1,000 | +40 |
| Total | 10,400 | 10,800 | +400 |
So bias = (10,800 − 10,400) ÷ 10,400 = +3.8%. In units, the forecast over-called demand by 400 across the quarter, or 33 a week on average. On a weighted basis this forecast is 94.2% accurate (5.8% WMAPE), a respectable number, and it still bought 400 units of stock nobody sold.
Look at where the 400 units sit. Weeks 6 and 10 contribute +190 and +160, which is 350 of the 400. The other ten weeks net to +50, a bias of +0.5%. The forecast treats a post-promotion week as a week at 400 units, and demand keeps coming in nearer 220. That is a modeling gap in one demand state, and it is invisible in the headline figure. A planner who responded to “+3.8% bias” by trimming every week’s forecast by 3.8% would push the ten normal weeks into under-forecasting and leave the two trough weeks still 150 units high.
Forecast bias and tracking signal calculator
Enter actual and forecast demand by period, or paste two columns from a spreadsheet. The calculator returns bias, mean error, MAD and a period-by-period tracking signal, and lets you exclude periods to see where the bias lives. Pre-filled with the 12-week example from the article.
| Period | Actual | Forecast | Error | Tracking signal |
Exclude |
|---|
Swipe the table sideways to reach the tracking signal and exclude columns.
You can also paste straight into an Actual cell: two columns of numbers fill down from that row.
Bias % = (Σ forecast − Σ actual) ÷ Σ actual. Tracking signal = running sum of errors ÷ MAD. Positive = over-forecast.
Bias in units
+400
Mean error per period
+33.3
MAD
50.0
WMAPE
5.8%
Final tracking signal
8.0
First period outside the band
Period 6
Bias is reported as a signed figure under the convention you pick. MAD is the mean absolute error over all included periods; the tracking signal at each period uses the MAD to date. Excluding a period removes it from every figure, which is how you test whether the bias lives in specific weeks.
Tracking signal: when bias becomes a problem
One quarter at +3.8% could be bad luck. The tracking signal is the test that tells you when it has stopped being luck.
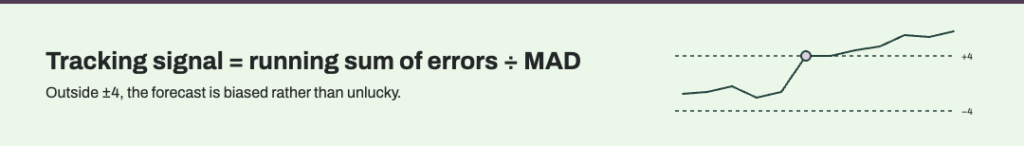
Tracking signal = running sum of forecast errors ÷ mean absolute deviation
The running sum of forecast errors (RSFE) adds up the signed errors week by week, so random misses cancel and persistent ones accumulate. The mean absolute deviation (MAD) is the average size of the errors regardless of sign. Dividing one by the other tells you how many “typical errors” the forecast has drifted from zero. An unbiased forecast wanders between about −2 and +2. The conventional alarm is ±4: outside that band, the probability that the drift is random is small enough that you should treat the forecast as biased and act.
| Week | Error | Running sum | MAD to date | Tracking signal |
| 1 | +50 | 50 | 50.0 | 1.0 |
| 2 | −10 | 40 | 30.0 | 1.3 |
| 3 | +20 | 60 | 26.7 | 2.2 |
| 4 | −40 | 20 | 30.0 | 0.7 |
| 5 | +10 | 30 | 26.0 | 1.2 |
| 6 | +190 | 220 | 53.3 | 4.1 |
| 7 | −20 | 200 | 48.6 | 4.1 |
| 8 | +30 | 230 | 46.2 | 5.0 |
| 9 | 0 | 230 | 41.1 | 5.6 |
| 10 | +160 | 390 | 53.0 | 7.4 |
| 11 | −30 | 360 | 50.9 | 7.1 |
| 12 | +40 | 400 | 50.0 | 8.0 |
For five weeks the signal sits comfortably inside the band. In week 6, the first post-promotion trough, it jumps to 4.1 and never comes back. By week 12 it reads 8.0, twice the alarm level. The signal did two useful things here: it fired in the week the problem first appeared rather than at quarter end, and it pointed at the cause, because the jump coincides with a specific demand event. When the tracking signal trips, the response is to find the demand state that tripped it and fix the model there, then reset the running sum so the signal can watch for the next drift.
Positive vs negative bias: what each costs
Positive bias (over-forecasting) fills the warehouse. Every week the forecast runs high, replenishment orders run high, and the difference lands in stock. Over a quarter it is 400 units. Over a year it is working capital plus the cost of excess inventory that follows it: storage, insurance, markdowns and write-offs when the item ages out. The inventory side of the Accuracy Report is a measure of exactly this, since what a better forecast is worth in the deployments it covers showed up first as overstock reduction.
Negative bias (under-forecasting) empties the shelf, then hides the evidence. A forecast that runs low produces stockouts, and a stockout week records the units you had, not the units customers wanted. Next year’s model learns from that history and forecasts low again. This censored-demand loop is the reason persistent under-forecasting is harder to detect than persistent over-forecasting: the warehouse shows you excess stock, but nothing shows you the sale that never happened unless you go looking for the stockout days and correct the history.
Neither direction is safe. Teams that fear stockouts drift positive, teams measured on inventory drift negative, and that is why bias belongs on the dashboard as a signed measure of its own rather than folded into a service level debate.
Where forecast bias comes from
Four sources account for most of the bias we see in planning teams, and the worked example adds a fifth.
Manual overrides and sales optimism. The statistical forecast says 1,000 and the demand review raises it to 1,050 because the account manager is confident. Repeated across SKUs and months, the overrides lean one way. In the Accuracy Report’s deployments, manual planning effort fell 70% once planners trusted the baseline, and fewer touches is also fewer places for a lean to enter.
Sandbagged targets. When the forecast doubles as a quota, the people who own it have reasons to set it low, and the supply plan inherits the gap.
Promotion uplift applied twice. The model has learned last year’s promotion from history, and the planner adds the uplift again on top. The forecast for the promotion week is then high by the whole uplift, and the post-promotion trough is missed entirely.
Stockouts recorded as low demand. The censored-demand loop described above. The history says demand was 180 in a week when the shelf was empty by Wednesday, and every model trained on that history under-forecasts the next one.
A demand state the model does not have. Our example’s bias comes almost entirely from two post-promotion weeks. The model has no concept of “the week after a promotion,” so it forecasts a round 400 and demand comes in at 210 and 240. In practice this is the source we find most often: the lean is specific to a state, such as post-promotion, holiday-adjacent or end of quarter, and it only shows up when you split bias by that state.
How to fix forecast bias
Measure bias per SKU and per demand state, as a signed number, every cycle. A portfolio bias near zero can hide an A item at +12% and another at −9%. Split by SKU, by customer where it matters, and by demand state (promotion, post-promotion, normal). The split is what turns “we have bias” into “the post-promotion forecast is 150 units high.”
Measure bias per override. Record the statistical number and the final number separately, and compute bias on each. Running forecast value added on every touch does this for accuracy. Do the same for direction. An override step with a consistent positive bias is a step to remove, whatever the accuracy metric says.
Correct stockout-censored history before retraining. Flag the periods where inventory was zero, and replace recorded sales with an estimate of demand (from pre-stockout run rate, from comparable stores, or from the days in stock). Otherwise the fix for under-forecasting is being trained away every year.
Model the demand states you are leaning in. If bias concentrates in post-promotion weeks, give the model a post-promotion feature. If it concentrates around holidays, give it the holiday calendar. The forecast cannot stop leaning in a state it cannot see.
Reset the tracking signal after each fix. A tracking signal carries the old running sum forward, so a fixed forecast can still read as biased for weeks. Reset the sum, keep the threshold, and let it watch for the next drift.
DemandForecast.ai does most of its work in exactly this part of the planning cycle. The platform forecasts from the drivers that move demand, including promotions, price and the calendar, so a post-promotion trough is modeled rather than averaged over, and it monitors its own drift: change monitoring and data drift detection flag when model behavior has moved or source data has gone stale, which is the tracking signal’s job done continuously and per SKU. Because every forecast comes with its drivers explained, planners can see why a number changed before deciding to override it, and the demand planning process ends up with fewer touches and fewer places for a lean to enter. The accuracy side of that is measured: across 15 head-to-head deployments in the Accuracy Report, the AI forecast beat the incumbent in every case reviewed, with forecast error reduced by 14% to 56%.
Forecast bias vs forecast accuracy
Accuracy tells you how big the miss is. Bias tells you which way it keeps going. A forecast can score well on one and badly on the other: our example is 94.2% accurate on a weighted basis and biased by +3.8%, and the bias is the more expensive of the two numbers because it compounds into stock. Track both, on the same dashboard, with bias kept as a signed figure. For the accuracy side, including MAPE, WMAPE and forecast value added on this same dataset, see our guide to forecast accuracy metrics.
If your bias report shows one number for the whole portfolio, the useful next step is to split it by demand state and see where the lean actually lives. Request a demo and we will run that split on a sample of your SKUs.