Improving demand forecast accuracy means closing the gap between the units you planned for and the units customers bought, at the level and lead time your supply plan is built on. Most guides to the subject offer a list of tips, and most of those lists are written for finance teams forecasting revenue rather than planners forecasting SKUs.
We think the list is the wrong shape. Accuracy fixes have an order of operations, because each one changes what the next one measures. Measure at the wrong level and the problem looks half its size. Chase error before removing bias and you tune a forecast that leans. Judge a model on history that still contains last year’s stockouts and you will reject the model that was right. So the nine fixes below come in the order to try them, each with the symptom that says it applies and a check you can run in twenty minutes. The ninth is the only one that costs money, and a planner who follows the order usually finds that two or three of the nine account for most of the gap.
What a forecast accuracy problem actually looks like
An accuracy problem rarely announces itself as a bad number. It arrives as one of four symptoms planners recognize on sight.
Chronic excess on some items alongside stockouts on others, in the same category and the same month, which means the forecast is wrong in both directions at once. Planners overriding nearly every line before the plan goes out. An accuracy KPI nobody in the room believes, usually because it is reported at a level no one buys at. And error that jumps after every promotion and takes a month to settle.
Each of those symptoms points at a different fix. That is why the order matters more than the length of the list.
Before you fix anything: a 20-minute diagnosis
Five steps, run once, tell you which of the nine fixes apply.
- Pull twelve months of forecast versus actual at the level and lag you buy at. SKU by location by week, using the forecast that was frozen when the order was placed, which is often not the one in the monthly deck.
- Compute WMAPE and bias on that cut. WMAPE for the size of the error, bias for its direction. If you need the formulas, our guide on how to measure forecast accuracy at the level you buy has them.
- Sort by error contribution, highest first. Absolute error multiplied by unit cost. The top 10% of lines usually carry over half the cost of error, and they are the lines to read.
- Tag promotion weeks and stockout weeks. A column for each. Then compute WMAPE with and without them, and compare.
- Compare the statistical baseline with the published number. Score the system’s untouched forecast and the final consensus forecast against the same actuals. The difference is what the review process added or subtracted.
Step 1 tests fix 1. Step 2 points at fix 2. Step 4 points at fixes 3 and 4. Step 3 feeds fixes 5 and 6. Step 5 is fix 7 in miniature.
How to improve demand forecast accuracy: 9 fixes in order
| # | Fix | Symptom that says you need it | How to check it in 20 minutes | Effort | Deep dive |
| 1 | Measure at the level and lag you buy at | Accuracy looks fine in the monthly deck while buyers complain about stock | Re-score last quarter at SKU-location-week, frozen at order lag | Low | Measuring accuracy |
| 2 | Remove bias before chasing error | Tracking signal sits outside its limits; the forecast leans one way month after month | Sum the signed errors by month and plot them | Low | Forecast bias |
| 3 | Clean stockout-censored history | Forecasts run low on exactly the items that ran out last season | List last year’s stockout weeks and compare their recorded sales with the weeks around them | Medium | Promotion and stockout effects |
| 4 | Put the promotion and price calendar into the model | The worst-error weeks are promotion weeks and the weeks right after | Score WMAPE with and without promotion weeks | Medium | The promotion calendar test |
| 5 | Match the method to the segment | One method runs on every SKU, fast movers and long tail alike | Split WMAPE by ABC class and by demand variability | Medium | ABC XYZ, intermittent demand |
| 6 | Cut drivers that don’t earn their place | The model tracks 15 to 20 variables and changes behavior every quarter | Remove one variable, re-score a held-out period, repeat | Medium | Demand drivers |
| 7 | Stop overrides that subtract value | Forecast value added is negative at the consensus or executive step | Score the baseline and the final forecast against the same actuals | Low | FVA on the accuracy page |
| 8 | Commit at the horizon you can actually forecast | Error explodes beyond a few months, yet orders are placed at 12 | Score accuracy by forecast horizon, one row per month out | Medium | Accuracy by horizon |
| 9 | Benchmark a new model against your incumbent | Fixes 1 to 8 are done and accuracy has plateaued | Run a second model on the same SKUs and hold-out, compare | High | Benchmarks against the incumbent |
1. Measure at the level and lag you buy at
Most accuracy reports are produced at the level that makes the number look best: monthly, by category, scored against the latest forecast instead of the one frozen when the purchase order went out. Errors at SKU and location cancel on the way up, and a forecast revised two days before month end is almost always right. The symptom is a monthly deck in the 80s while the buyers complain about stock. The check is to re-score last quarter at SKU-location-week, frozen at the order lag. The number will fall, and it will become useful. Everything else in this list is measured on that cut.
2. Remove bias before chasing error
A forecast that misses by 6% at random and a forecast that misses by 4% in the same direction every week have different problems, and the second is the expensive one, because every week adds stock nobody needed or leaves demand unserved. The symptom is a tracking signal outside its limits, or simply a forecast that has leaned the same way for three months. The check is to sum the signed errors by month and look at the sign. Our guide to forecast bias and the tracking signal covers the alarm threshold and where bias usually comes from. The action is to find the demand state where the lean lives, such as post-promotion weeks, and fix the model there. Trimming every forecast by the average fixes the wrong weeks.
3. Clean stockout-censored history
A week in which the item ran out on Wednesday records three days of demand as seven. The next model learns that the item sells less than it does, forecasts low, and causes the next stockout. The symptom is a forecast that runs low on exactly the items that ran out last season, which planners describe as “the system never learns.” The check is to list last year’s stockout weeks from the inventory ledger and compare their recorded sales with the weeks on either side. The action is to replace recorded sales in those weeks with an estimate of demand before training, and to keep the stockout flag as a column the model can see.
4. Put the promotion and price calendar into the model
Promotions are the biggest single source of error in most consumer categories, and the classical methods cannot see them, so they either smooth the lift away or learn last year’s promotion as seasonality and forecast it on the wrong date. The symptom is a worst-error list that is mostly promotion weeks and the weeks right after. The check is to score WMAPE with and without those weeks. If the gap is large, feed the model the calendar: promotion flags, price, display and the post-promotion week, as inputs it can learn from. The section below shows what that is worth.
5. Match the method to the segment
One method for every SKU means the method is wrong for most of them. A stable fast mover, a seasonal item, a promoted item and a long-tail part that sells twice a quarter need different approaches, and the long tail will score badly on any percentage metric no matter what you run on it. The symptom is a single model and a single accuracy target across the whole catalog. The check is to split WMAPE by ABC XYZ segmentation and look at the Z column. The action is to give the sparse series intermittent demand methods and a service-level KPI, and to stop judging them on the fast movers’ metric.
6. Cut drivers that don’t earn their place
More inputs feel like more accuracy, and past a small number they are the opposite. A model with twenty variables fits the noise in each of them, changes its behavior every quarter as the noise changes, and cannot be explained to the people who have to trust it. The symptom is a model that tracks 15 to 20 variables and keeps surprising the planners. The check is to remove one variable, re-score a held-out period, and repeat. Our work on why 4 drivers beat 20 explains the mechanism, and the Accuracy Report has the case: Nanit, a smart baby monitor maker, started with more than 20 variables its team was confident drove demand, and the model narrowed them to four that carried signal, reaching 80% accuracy across SKUs and channels.
7. Stop overrides that subtract value
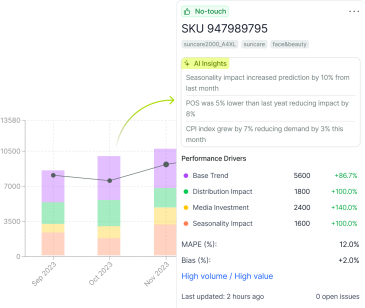
Every manual adjustment is a bet that the planner knows something the model does not. Some of those bets pay. Many do not, and the ones that do not are rarely measured. The symptom is a forecast value added figure that goes negative at the consensus or executive step, or a planning team touching more than half the lines every cycle. The check is the fifth diagnosis step: score the statistical baseline and the final forecast against the same actuals. The action is to remove the override steps that subtract value and keep the ones that add it. In the Accuracy Report’s deployments, manual planning effort fell 70% on average once planners trusted the baseline, and at Mars 75% of forecast volume qualified as touchless.
8. Commit at the horizon you can actually forecast
Error grows with horizon, and it grows faster than most planning calendars assume. In the Accuracy Report, an electrical components distributor with 7,500 stocked SKUs measured accuracy by forecast horizon at 58% to 73% one month out and 34% to 53% twelve months out, by product segment. The symptom is error that explodes beyond a few months while the business still places firm orders at twelve. The check is one row of accuracy per month out. The action is to commit firm quantities only at the horizon where accuracy holds, and to plan the longer horizon with ranges and options in place of single numbers.
9. Benchmark a new model against your incumbent
When fixes 1 to 8 are done and accuracy has stopped moving, the incumbent method has reached its ceiling, and the only remaining question is whether a different model has a higher one. The symptom is a plateau. The check is a benchmark: a second model on your own SKUs, at the lag you order at, scored on the same hold-out as the incumbent. The action depends on the result, which is the point. This is the one fix that costs money, and the last section covers what our report’s benchmarks showed.
Inputs beat algorithms: the promotion calendar test
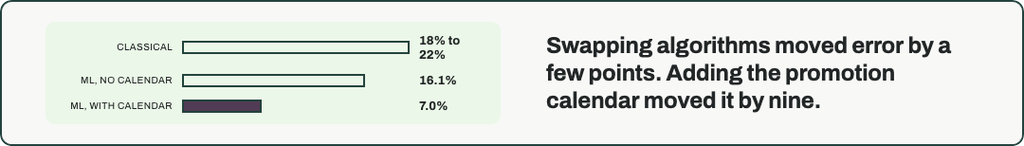
Fix 4 is worth a number. We ran six forecasting methods on one SKU with 104 weeks of history, ten promotions, a price change and a seasonal peak, scored on a 13-week hold-out. The five classical methods landed between 18% and 22% WMAPE. The gradient boosting model with the promotion, price and holiday flags as inputs scored 7.0%. The same model, same settings, same training window, with those flags removed, scored 16.1%, inside the classical pack.
| Method | Hold-out WMAPE |
| Classical pack (naive, seasonal naive, moving average, Holt-Winters, seasonal ARIMA) | 18% to 22% |
| Machine learning, same model, no promotion, price or holiday inputs | 16.1% |
| Machine learning, same model, with the calendar as inputs | 7.0% |
Swapping algorithms moved error by a few points. Adding four columns the planner already had moved it by nine. The full test, week by week, is in our post on what the promotion calendar does to forecast error, and it is the reason fixes 3 and 4 sit ahead of fix 9: a new model fed the same thin inputs will plateau in the same place.
What doesn’t improve forecast accuracy, even though it looks like it does
Three changes raise the accuracy number without raising the forecast.
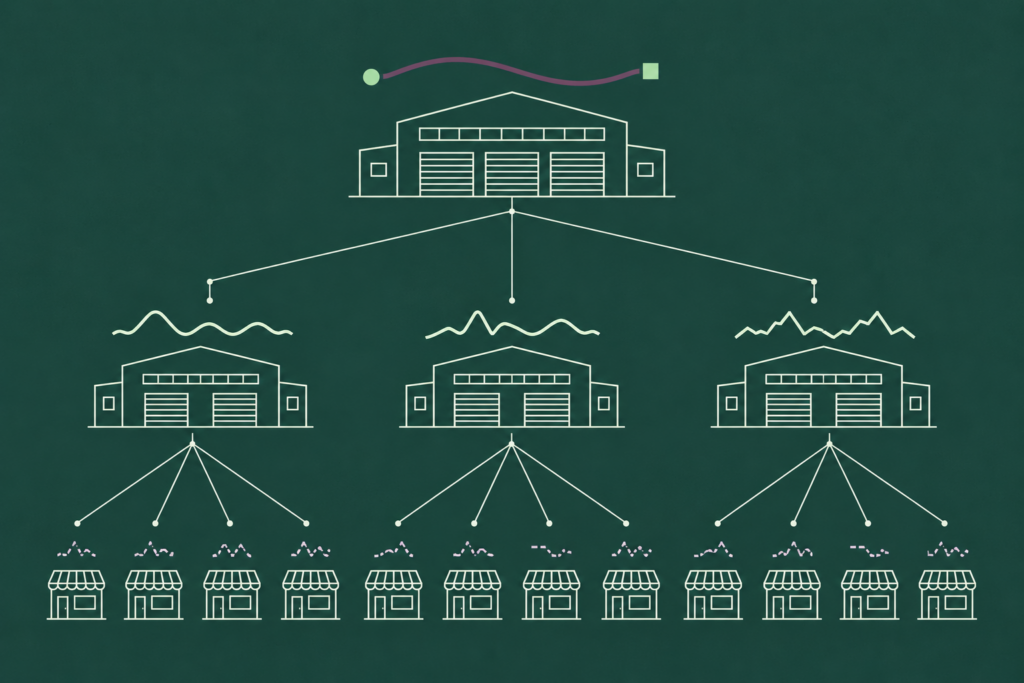
Measuring at a higher aggregation level. Errors cancel as they roll up. A forecast that is 72% accurate at SKU-location can be 91% accurate at category-month, and the second number buys nothing, because no one orders a category.
Excluding promotion weeks from the score. The weeks that are hardest to forecast are the weeks that cost the most when the forecast is wrong. Dropping them produces a clean number on the weeks that did not matter.
Changing the metric mid-year. Moving from MAPE to WMAPE, or from a one-month lag to a one-week lag, will move the number, and the move says nothing about the forecast. Pick the metric, the level and the lag once, write them down, and keep them until the next annual review.
When to replace the forecast instead of tuning it
Fixes 1 to 8 are free, in the sense that they need planner time and a spreadsheet. Run them first. When they are done and the number has stopped moving, the incumbent has reached its ceiling, and the only way to learn whether that ceiling is yours or the method’s is to put a second model beside it on the same SKUs.
Our 2026 Demand Forecasting Accuracy Report did that fifteen times, across retail, distribution, manufacturing and consumer goods. In every deployment the AI forecast was benchmarked against the incumbent forecast the company already relied on, and it produced less error in 15 of 15, with reductions from 14% to 56% and an average of 32%. The incumbents included statistical baselines, planner-adjusted forecasts and S&OP consensus numbers: the forecasts fixes 1 to 8 had already been applied to.
DemandForecast.ai is the model on the other side of those benchmarks. It runs an ensemble per SKU, takes the promotion calendar, price and the other drivers that fixes 3 and 4 put into the data, keeps the drivers that earn their place in the way fix 6 describes, and shows planners which inputs moved each forecast, so the override decision in fix 7 is made with the reasoning in view. The right way to evaluate it is fix 9: on your SKUs, at your order lag, against your current number.
If you have worked through the ladder and the number has plateaued, request a demo and we will set up the benchmark on a sample of your own SKUs.